predictive
# Predictive Failure Detection Using Time-Series Signals
# Predictive Failure Detection Using Time-Series Signals
predictive
# Predictive Failure Detection Using Time-Series Signals
predictive
By feeding predictions into Grafana dashboards and Prometheus alerts, SREs can automate rollbacks or scaling, embodying predictive DevOps principles.
predictive
The average time to repair operational issues stands at 220 minutes, according to industry reports—a costly delay when enterprises face hourly downtime costs exceeding $1 million. Traditional reactive monitoring catches problems after they impact users. But what if…
predictive
# Predictive Failure Detection Using Time-Series Signals: A Guide for DevOps Engineers and SREs
predictive
In modern DevOps and SRE practices, predictive failure detection using time-series signals transforms reactive firefighting into proactive resilience. By analyzing metrics like CPU usage, latency, or sensor data from infrastructure, teams can forecast failures hours or days ahead,…
proactive
In modern DevOps and SRE practices, proactive anomaly detection using metrics shifts monitoring from reactive firefighting to predictive issue resolution. By leveraging machine learning on time-series metrics, teams can identify deviations from normal patterns before they impact users,…
root
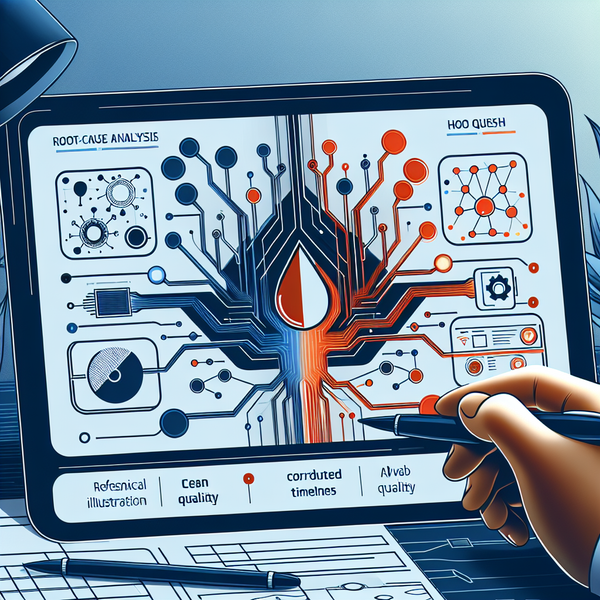
Root-cause analysis using correlated timelines empowers DevOps engineers and SREs to swiftly pinpoint failures in complex systems by visualizing event sequences across services, logs, metrics, and traces. This technique transforms chaotic incident data into actionable insights, reducing mean…
root
In modern DevOps and SRE environments, root-cause analysis using correlated timelines transforms chaotic incident investigations into structured, efficient processes. By aligning events from logs, metrics, traces, and deployments on a unified timeline, teams pinpoint failures faster, reducing mean…